Category: AI News
-

Paged Attention in Large Language Models LLMs
[ad_1] When running LLMs at scale, the real limitation is GPU memory rather than compute, mainly because each request requires a KV cache to store token-level data. In traditional setups, a large fixed memory block is reserved per request based on the maximum sequence length, which leads to significant unused space and limits concurrency. Paged…
-

The three disciplines separating AI agent demos from real-world deployment
[ad_1] Getting AI agents to perform reliably in production — not just in demos — is turning out to be harder than enterprises anticipated. Fragmented data, unclear workflows, and runaway escalation rates are slowing deployments across industries. “The technology itself often works well in demonstrations,” said Sanchit Vir Gogia, chief analyst with Greyhound Research. “The…
-

Palantir AI to support UK finance operations
[ad_1] UK authorities believe improving efficiency across national finance operations requires applying AI platforms from vendors like Palantir. The country’s financial regulator, the FCA, has initiated a project leveraging AI to identify illicit activities. The FCA is currently testing the Foundry platform from Miami-based software vendor Palantir. This three-month pilot costs upwards of £30,000 per…
-
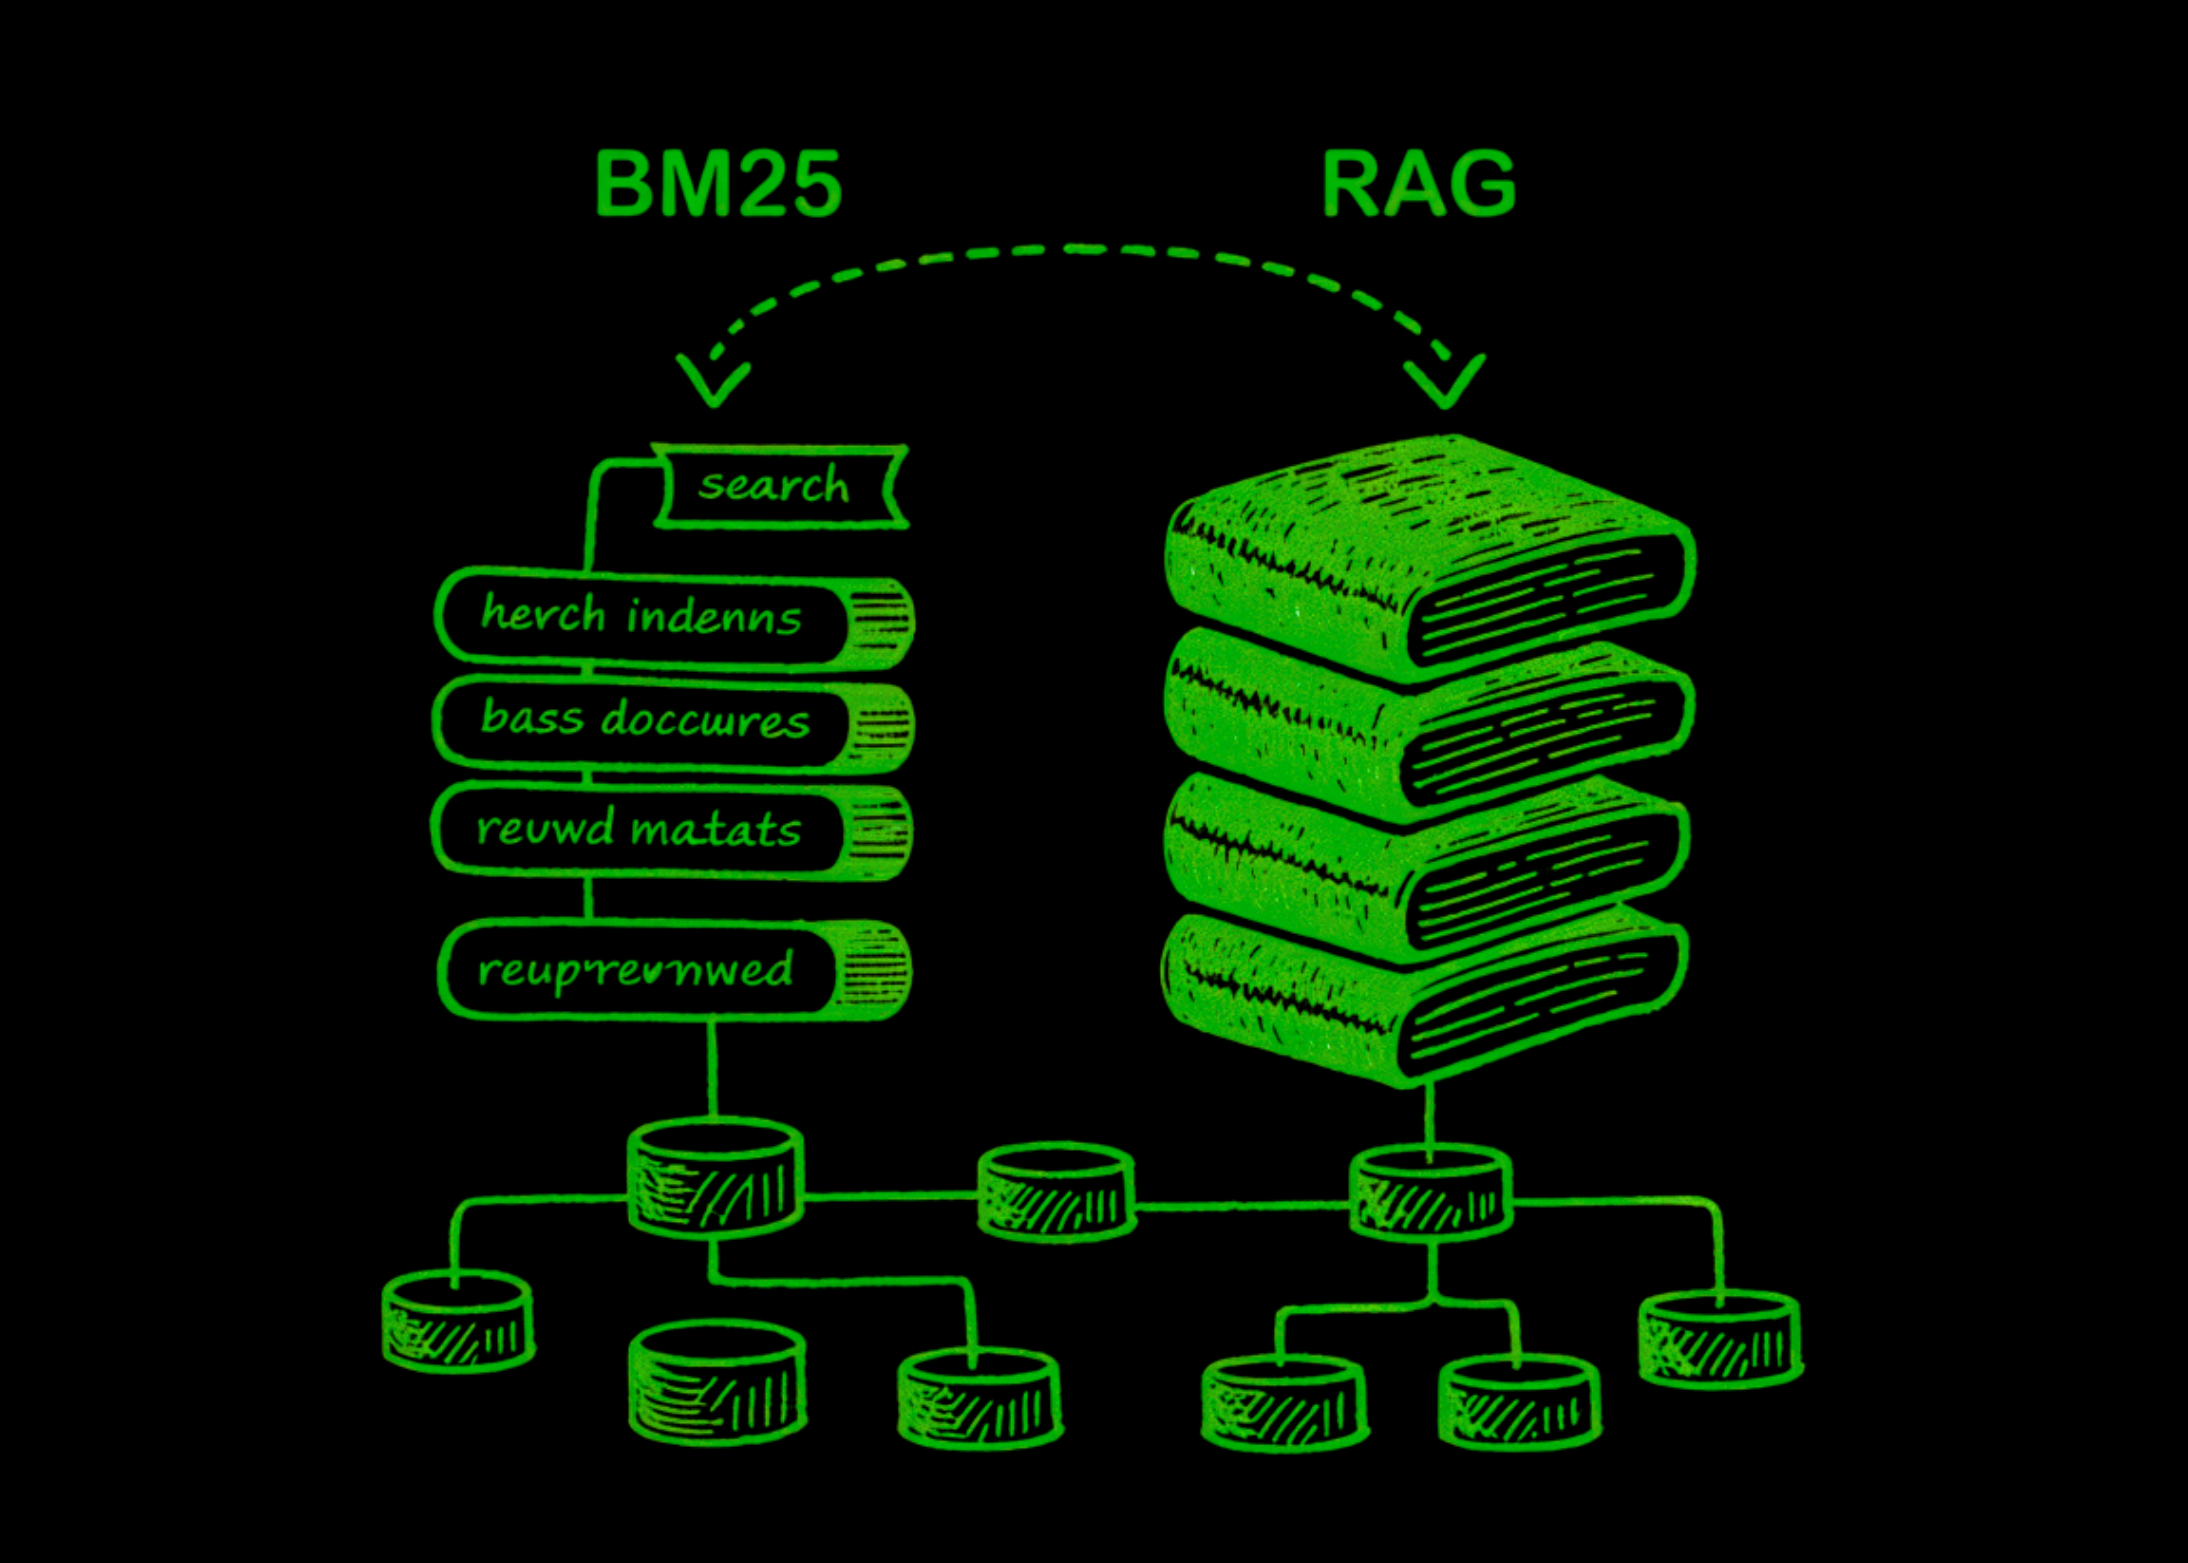
How BM25 and RAG Retrieve Information Differently?
[ad_1] When you type a query into a search engine, something has to decide which documents are actually relevant — and how to rank them. BM25 (Best Matching 25), the algorithm powering search engines like Elasticsearch and Lucene, has been the dominant answer to that question for decades. It scores documents by looking at three…
-
You thought the generalist was dead — in the 'vibe work' era, they're more important than ever
[ad_1] Not long ago, the idea of being a “generalist” in the workplace had a mixed reputation. The stereotype was the “jack of all trades” who could dabble in many disciplines but was a “master of none.” And for years, that was more or less true. Most people simply didn’t have access to the expertise…
-

Mastercard keeps tabs on fraud with new foundation model
[ad_1] There’s a risk to the multi-function LTM approach, of course: A failure in a widely-deployed model could have system-wide consequences, which goes some way to explain Mastercard’s strategy of applying its technology alongside existing detection systems – at least, for the present. Mastercard hopes to increase the scale of the data used on the…
-

Safely Deploying ML Models to Production: Four Controlled Strategies (A/B, Canary, Interleaved, Shadow Testing)
[ad_1] Deploying a new machine learning model to production is one of the most critical stages of the ML lifecycle. Even if a model performs well on validation and test datasets, directly replacing the existing production model can be risky. Offline evaluation rarely captures the full complexity of real-world environments—data distributions may shift, user behavior…
-
Three ways AI is learning to understand the physical world
[ad_1] Large language models are running into limits in domains that require an understanding of the physical world — from robotics to autonomous driving to manufacturing. That constraint is pushing investors toward world models, with AMI Labs raising a $1.03 billion seed round shortly after World Labs secured $1 billion. Large language models (LLMs) excel…
-

NVIDIA Agent Toolkit Gives Enterprises a Framework to Deploy AI Agents at Scale
[ad_1] The NVIDIA Agent Toolkit is Jensen Huang’s answer to the question enterprises keep asking: how do we put AI agents to work without losing control of our data and our liability? Announced at GTC 2026 in San Jose on March 16, the NVIDIA Agent Toolkit is an open-source software stack designed to help enterprises…
-

LlamaIndex Releases LiteParse: A CLI and TypeScript-Native Library for Spatial PDF Parsing in AI Agent Workflows
[ad_1] In the current landscape of Retrieval-Augmented Generation (RAG), the primary bottleneck for developers is no longer the large language model (LLM) itself, but the data ingestion pipeline. For software developers, converting complex PDFs into a format that an LLM can reason over remains a high-latency, often expensive task. LlamaIndex has recently introduced LiteParse, an…